 Model launchAI modelsNews from
Alibaba releases its Qwen3.8 flagship as open weights
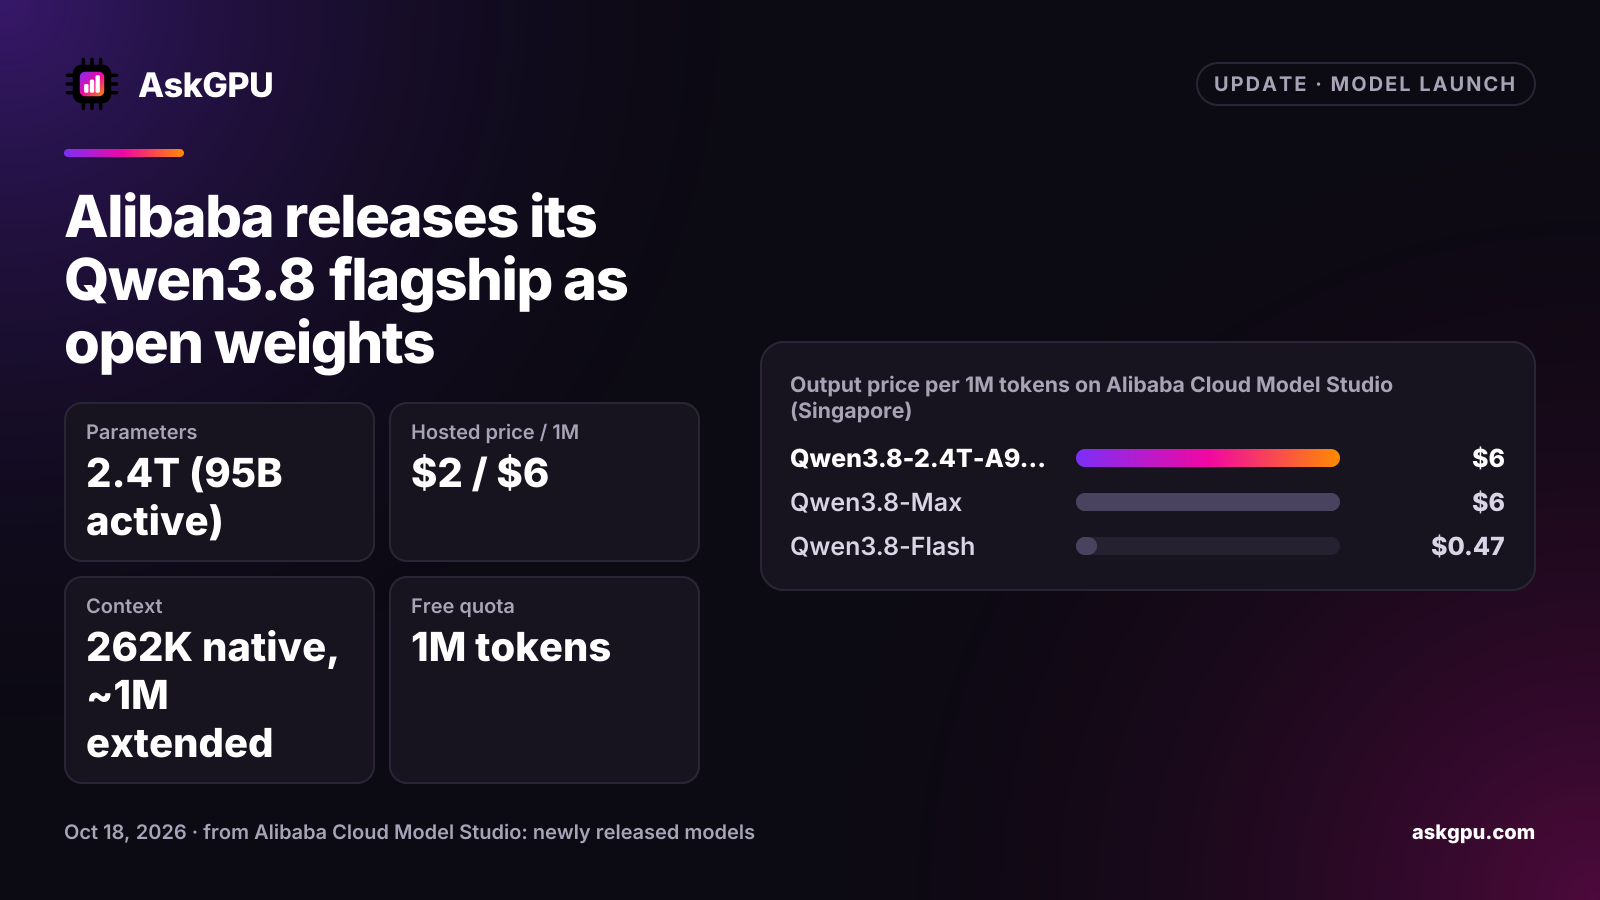
Alibaba added Qwen3.8-2.4T-A95B, the open-weight version of its Qwen3.8 flagship, to Model Studio on August 12, 2026. Hosted, it costs $2 input and $6 output per 1M tokens.
Alibaba’s Qwen team has released the flagship of its Qwen3.8 family as open weights. Alibaba Cloud
added the model, qwen3.8-2.4t-a95b, to its Model Studio API on August 12, 2026, ten days after it
launched the hosted Qwen3.8-Max there. The model card calls it the first Qwen-Max-class model released with open
weights.
What it is
| Qwen3.8-2.4T-A95B | |
|---|---|
| Architecture | Sparse mixture of experts: 2.4T total, about 95B active |
| Context | 262,144 tokens natively, extendable to 1,010,000 |
| Input / output | Text only |
| Thinking | Always on; depth set by reasoning_effort (low, medium, xhigh) |
| License | Listed on Hugging Face as “qwen3.8-max” |
The hosted Qwen3.8-Max, by contrast, has native image understanding and a 1M-token context by default.
Qwen reports 86.6 on Terminal Bench 2.1, 67.7 on SWE-bench Pro and 92.6 on GPQA Diamond for the open model. These are the vendor’s own figures.
What it costs to use hosted
International (Singapore) prices on Alibaba Cloud Model Studio, per 1M tokens:
| Model | Input | Output |
|---|---|---|
| Qwen3.8-2.4T-A95B | $2.00 | $6.00 |
| Qwen3.8-Max | $2.00 | $6.00 |
| Qwen3.8-Flash | $0.15 | $0.47 |
Each model has a single price band up to 1M tokens, so long prompts don’t cost more per token. Model Studio gives 1M free tokens per model in the Singapore region, valid for 90 days. All three models also support a context caching discount on input tokens.
Who it is for
The open weights let you run the model on your own servers or with a host of your choice, so your prompts don’t have to go to Alibaba. At 2.4 trillion parameters, though, self-hosting it takes a large GPU cluster; for most teams, the hosted API or a smaller model is the practical choice.
What to do
Read the license on the model card before you use the weights in a product. If you only need the API, compare Qwen3.8-Max with Qwen3.8-Flash on your own tasks: Flash costs less than a tenth as much per output token.
- Qwen3.8-2.4T-A95B (open)$6
- Qwen3.8-Max$6
- Qwen3.8-Flash$0.47
Sources
Read on . Prices are in US dollars. How we check facts